Five Things Building an Air Quality Model Taught Me About Shipping AI Products
 Jack Seagrist
A few years ago, my partner Karthik and I built a deep learning model for our CS 230 final project at Stanford. The goal was straightforward: could we use cheap, widely available weather data to forecast PM2.5 air pollution in the Bay Area?
The model worked, but what stuck with me more was the process of getting there. We went through four model versions, debugged bias problems, watched performance improve and then plateau, and made a lot of tradeoff decisions without an obvious right answer. Now that I work as a PM, I keep coming back to those lessons when building AI features. Here are five of them.
A little context on the project
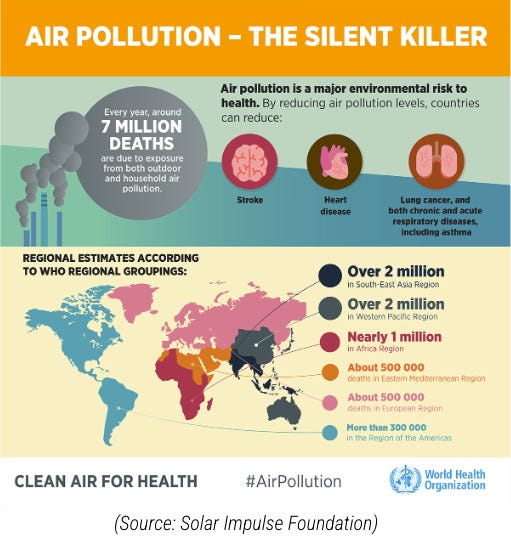
Air pollution causes 5 million deaths per year globally and costs the world economy an estimated $225 billion annually [1]. The primary metric is PM2.5, fine particulate matter small enough to enter the bloodstream. The problem: the sensors that measure it are expensive and can’t be deployed everywhere.
Our question:
Can a neural network trained on freely available weather data accurately forecast PM2.5, even in locations it has never seen?
We pulled five years of daily data (2015–2019) from CIMIS weather stations and EPA air quality monitors across the Bay Area. We built an LSTM, a type of recurrent neural network designed for sequential data, and iterated through four model versions, tuning architecture and loss functions each time. Our final model reduced RMSE from 6.99 to 3.70, and generalized to Oakland even though the model had never trained on East Bay data.
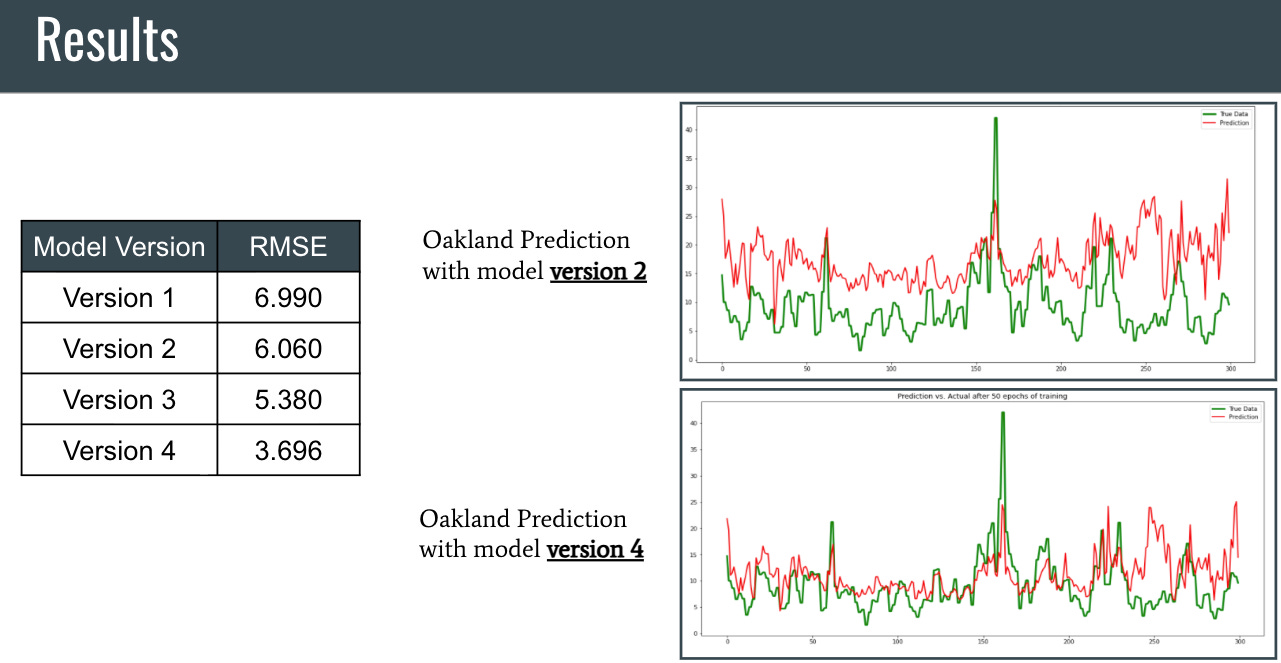
Generalizing to a location the model had never seen was the result I was most proud of.
1. Define your baseline before you touch the model
Before we trained anything, we needed to answer a simple question: what does “good” look like? Without a baseline, you have no way to know whether your model is actually doing anything useful.
We established our baseline performance using the simplest reasonable approach, then used RMSE as our consistent measure across every model version. Every improvement was relative to something concrete. When version 3 dropped RMSE from 6.06 to 5.38, we knew exactly what that meant.
As a PM, I now treat defining a baseline as a requirement before any new development. Before we discuss solutions, vendors, or timelines, I want to know: what does the system do today, how do we measure it, and what would a simple version achieve? If the team can’t answer those questions, we’re not ready to build.
2. Iteration is a product process too
We didn’t get to RMSE 3.70 in one shot. We ran four model versions, each informed by what the previous one got wrong.
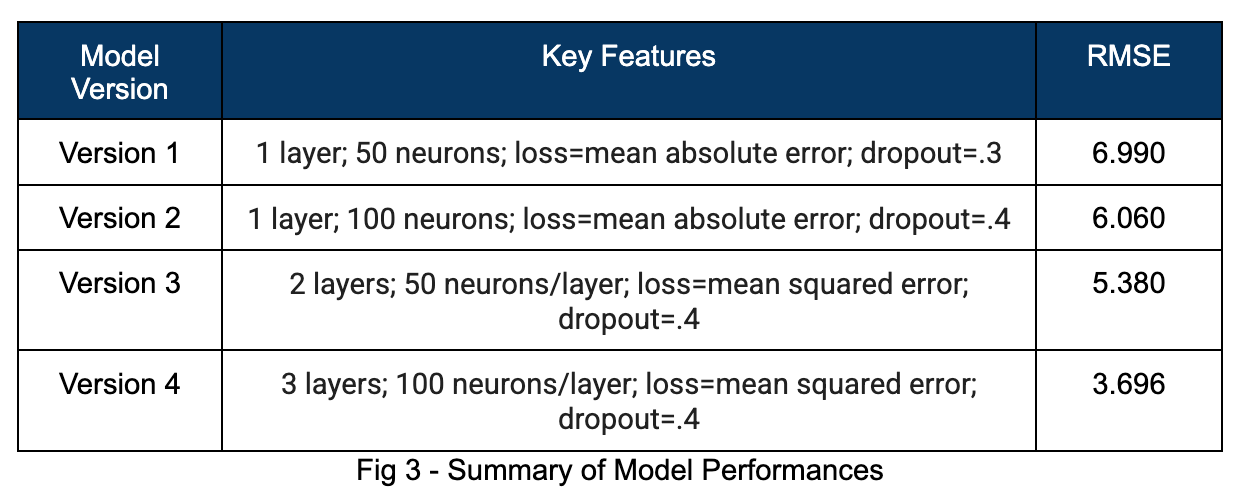
Version 2 had high bias. It tracked the trend but consistently underestimated PM2.5 spikes. Adding more layers helped more than adding neurons, which version 3 confirmed and version 4 held up at scale.
What I learned is that decisions like switching loss functions, adding layers, and adjusting dropout weren’t just engineering calls. They had product consequences too. Deeper networks are more accurate but slower to train and harder to explain. MSE loss penalizes large errors more than MAE, which matters when the dangerous edge cases are precisely the big spikes.
I see the same kinds of tradeoffs when picking between model vendors, choosing evaluation criteria, or scoping the first release of an AI feature. The questions are the same: what are we optimizing for, what are we giving up, and are we choosing that on purpose?
3. Watch the gap between validation and production
Our model performed well on our test stations. But it had a real limitation baked in from the start: we had no emissions data. PM2.5 isn’t just a function of weather. It’s also driven by traffic, industrial activity, wildfires, and agricultural burning. We were modeling the signal we could measure, not the full system.
Because of that, the predictions followed the overall trend but missed the spikes, which are the high PM2.5 days that matter most for public health.
I've seen the same thing happen in product work outside of machine learning. A feature works perfectly in staging, then production throws messier inputs and more edge cases at it. Often the thing the model can't see, or the edge case QA didn't catch, ends up mattering the most.
As a PM, the question I now ask before anything ships is: what is this solution blind to, and what happens when users hit that edge? That question shapes rollout strategy, fallback design, and how we communicate confidence to stakeholders. It doesn’t have to block a launch, but it should shape how we design it.
4. Pick your metric carefully
Our choice of RMSE as the primary metric wasn’t arbitrary. We were solving a regression problem where the size of errors mattered. A model that consistently underestimates by 2 µg/m³ is very different from one that’s usually right but occasionally off by 15. RMSE captures that distinction. Mean Absolute Error doesn’t.
Picking the wrong metric would have changed what we built. If we had optimized for classification accuracy (above/below a threshold) instead of RMSE, we would have ended up with a model that looked better on paper but was less useful for anyone trying to understand actual pollution levels.
The same goes for PM work. The evaluation criteria you set before development determine what the team optimizes for, and therefore what you ship. I now spend real time on metric definition upfront and bring engineering and design into that conversation, instead of leaving it as a QA step at the end.
5. Be upfront about limitations
Our conclusion didn’t oversell the results. We were clear: the model generalizes well within Bay Area microclimates, but the training set is small, emissions data is absent, and performance in different climate regions is untested. We said what the model could do and what it couldn’t.
That felt like the right call for a class project, and I think it’s the right call as a PM too.
When software is presented as more capable than it is, you lose trust quickly with users, stakeholders, and the engineers who have to maintain it. Being upfront about limitations is less exciting than a clean demo, but it saves a lot of cleanup later.
Why this still matters to me
Air quality prediction from weather data isn’t a solved problem, and what we built in CS 230 was a starting point, not a product. But the habits I picked up (setting baselines, iterating deliberately, evaluating honestly, and planning for the gap between validation and production) have carried over to almost everything I work on.
I definitely didn’t expect a deep learning class to shape how I think about product management, but here we are. Thanks for reading!
References
[1] World Bank. The Cost of Air Pollution: Strengthening the Economic Case for Action. 2016.
[2] CIMIS. California Irrigation Management Information System. cimis.water.ca.gov
[3] EPA Outdoor Air Quality Data. epa.gov/outdoor-air-quality-data
[4] Kim, H.S. et al. Forecasting Air Quality Using LSTM Networks. arXiv:1804.07891, 2018.
[5] Reddy, V. Deep Air: Forecasting Air Pollution in Beijing, China. UC Berkeley iSchool, 2018.